Discover 169 technologies from leading innovators around the world.
Cambricon MLUarch03 is the company’s published AI processor architecture for machine-learning accelerators.
AI & HPCData CenterView Technology
Cerebras Wafer-Scale Engine 3 is a wafer-scale AI processor: one chip occupying an entire 300mm wafer for large-model training and inference.
AI & HPCData CenterView Technology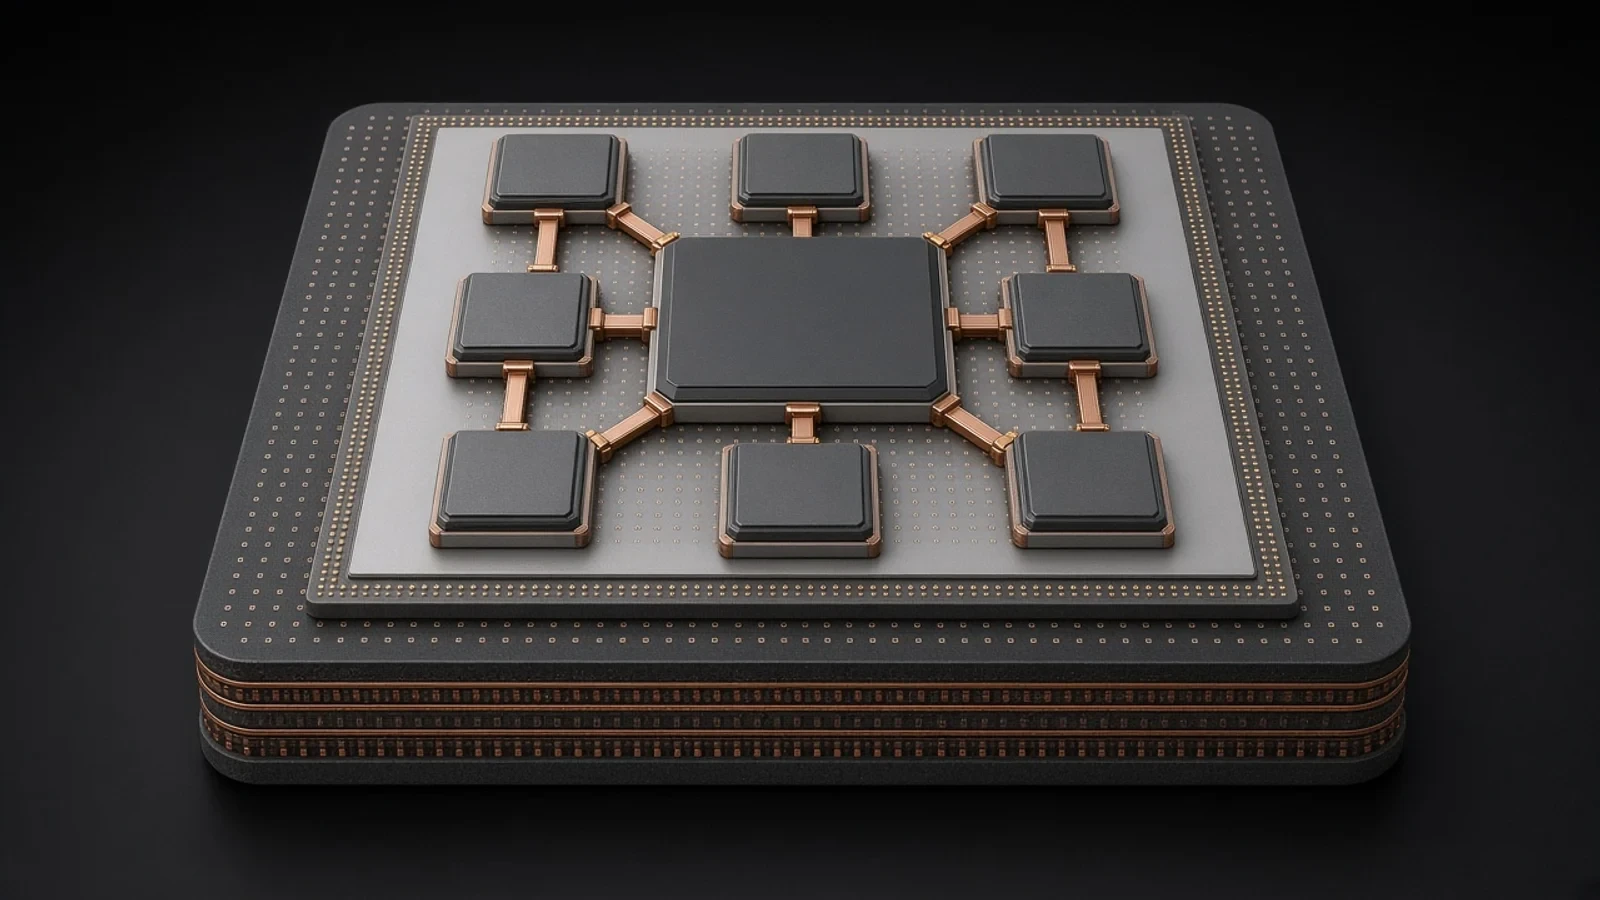
Infinity Fabric is AMD’s coherent on-package and multi-die interconnect, linking CPU core-complex dies to a central I/O die and, in multi-socket systems, across packages. Official EPYC architecture documents describe CCD–IOD GMI links and xGMI.
AI & HPCData CenterConsumer ElectronicsView Technology
Trainium is AWS’s custom machine-learning training silicon, built around NeuronCore and used in EC2 Trn instances. Official AWS silicon pages describe purpose-built ML chips as part of AWS custom silicon.
AI & HPCData CenterView Technology
Azure Maia 100 is Microsoft's first in-house cloud AI accelerator: 105 billion transistors on 5 nm, for Azure training and inference.
AI & HPCData CenterView Technology
Blackwell is NVIDIA’s current data-center GPU architecture, built as a dual-die GPU with a 10 TB/s chip-to-chip interconnect. Official materials describe a two-reticle design manufactured on TSMC 4NP.
AI & HPCData CenterView Technology
BlueField is NVIDIA’s data processing unit: Arm cores, high-speed Ethernet/InfiniBand and hardware accelerators for networking, storage and security offload, isolated from the host CPU.
AI & HPCData CenterTelecommunicationsView Technology
Oryon is Qualcomm’s custom 64-bit CPU microarchitecture, including cache hierarchy, branch prediction, prefetch and later Flex Cache, designed in-house and scaled across Snapdragon platforms.
AutomotiveAI & HPCData Center+1View Technology
TPU7x (Ironwood) is Google Cloud's seventh-generation TPU, built for large-scale training and inference.
AI & HPCData CenterView Technology
NVIDIA NVLink is a high-bandwidth GPU-to-GPU interconnect and rack-scale fabric for AI training and inference. Distinct from NVLink-C2C chip-to-chip packaging links.
AI & HPCData CenterView Technology
NVIDIA NVLink-C2C is a high-bandwidth coherent chip-to-chip interconnect for processors, accelerators and custom silicon inside a package. Distinct from NVLink GPU-to-GPU fabric.
AI & HPCData CenterView Technology